AI Foundations, Part 4: An AI That Actually Touches Your Files
The difference between a chatbot and an agentic CLI tool isn't the conversation — it's that one of them can open a file, run your tests, and make the change itself.
A chatbot tells you how to fix the bug. An agentic CLI tool opens the file, fixes it, runs the tests, and tells you what it did.
That’s the entire distinction, and it’s a bigger one than it sounds.
What makes a tool “agentic”
Every AI chat interface you’ve used — ChatGPT, Claude.ai, whatever’s built into your phone’s keyboard — works the same way underneath. You type something, it generates a response, the response lands in a text box, and if you want anything to actually happen with that response, you’re the one who copies it, pastes it, opens the file, and makes the edit yourself. The model is a very capable author. It has no hands.
An agentic CLI tool gives it hands, and specifically gives it hands inside your own machine. It runs in your terminal, inside your actual project directory, with the ability to read files, edit them, execute shell commands, search your codebase, and chain all of that together into a multi-step task — without you narrating every single step along the way. You give it a goal. It figures out the sequence of file reads, edits, and command executions needed to get there, does them, and reports back.
The mechanism behind that isn’t mysterious or new — it’s the same tool-calling loop covered in the next post in this series, where a model can request that a function run and receive the result back into its context. What makes a coding tool “agentic” specifically is which functions it’s been handed: read_file, edit_file, bash, grep, glob — a toolkit aimed squarely at software project. Wire that toolkit to a capable model, put it in a loop that keeps running until the task is done, and you’ve built something categorically different from a chat window. Not a better chatbot. A different kind of program.
A chatbot describes the fix. An agentic tool goes and gets it. That’s not a matter of degree — it’s a different category of software.
Meet the actual tools
This isn’t one product, it’s a growing category, and the specific tools differ in real ways worth knowing.
Claude Code, Anthropic’s own terminal-based agent, launched in February 2025 alongside Claude 3.7 Sonnet as a limited research preview and has since become a full product — available in the terminal, inside IDEs, in a desktop app, and (this very post is a product of it) able to run tools like the browser automation and image generation used to build this site. It reads your entire project, plans an approach, edits across multiple files in one pass, runs your test suite, and iterates on failures without you babysitting each step.
Aider takes a different shape: an open-source, git-native pair programmer that’s editor-agnostic — it runs alongside VS Code, JetBrains, Vim over SSH, or a plain terminal split, rather than trying to be the whole environment. You tell it which files are “in the chat,” describe the change, and it edits those files directly, then makes an atomic git commit with a generated message for every change.
Both of these, along with OpenAI’s Codex CLI and the agent modes built into editors like Cursor and Windsurf, are answering the same underlying question in slightly different ways: how much of the actual engineering loop — not just the writing, but the running, checking, and fixing — can the tool do on its own before it needs you again. The gap between “assistant” and “agent” is exactly that loop, and it’s the subject of the rest of this post.
A persistent context file changes everything
The single highest-leverage habit in this whole space is keeping a persistent context file at the root of your project. Claude Code calls it CLAUDE.md. Aider works from your existing README and repo structure, or a project conventions file you point it at. Different tools, same idea: a plain-text file the assistant reads automatically at the start of every session, so you stop re-explaining your own project from scratch every single time.
# Project: Example Monitoring System

## Architecture
- Backend: Python API, containerized
- Database: Postgres with migrations
- Frontend: TypeScript SPA

## Coding Standards
- Type hints required on all functions
- Run the test suite before committing

## Domain Context
This system monitors operating parameters for industrial equipment.
Key parameters live in config/setpoints.yaml.

## File Map
- src/api/ — endpoints
- src/monitors/ — monitoring logic
- src/alerts/ — alert generation and routing
- tests/ — all test files
Write that once and every future session starts already knowing your architecture, your standards, and your domain — instead of starting from zero.
Why this actually works: the model has no memory of its own
Here’s the mechanical reason a text file has this much leverage. A language model doesn’t remember your last session. It doesn’t remember five minutes ago in this session, either, in the sense a person means “remember” — every single response is generated from scratch, off whatever text currently sits in its context window: the running transcript of the conversation, plus anything else that’s been loaded in alongside it. Close the terminal and reopen it tomorrow, and unless something deliberately re-loads your project’s context, the model that greets you knows nothing it didn’t know the day it finished training.
A persistent context file is the fix: it gets read into that context window automatically, at the start of every session, before you’ve typed a word. You’re not re-explaining your project — you’re letting the framework hand the model a document it already knows to read. The file itself has no memory either. What it has is the property of being reliably re-read, which produces the same practical effect as memory without requiring the model to have any.
This is also why a stale context file is worse than none — if it describes an architecture you refactored away from six months ago, you’re not saving the model time, you’re actively feeding it wrong information with the full authority of “this is how the project works.” Treat it like documentation, because that’s exactly what it is: written for a very literal, very fast new team member who reads it fresh every morning.
Permission is a dial, not a switch
Handing a program the ability to edit your files and run commands on your machine is not a small thing to hand over, and the tools in this category treat it that way — with graded control rather than an all-or-nothing switch.
Claude Code’s allow / deny / ask hierarchy
Claude Code’s permission system runs on three rule types, evaluated in a fixed order — deny, then ask, then allow — so a deny rule always wins regardless of what an allow rule elsewhere says:
{
  "permissions": {
    "allow": ["Bash(npm test)", "Bash(git status)", "Bash(git diff)", "Read", "Edit"],
    "ask": ["Bash(git push:*)"],
    "deny": ["Bash(rm -rf *)", "Read(./.env)"]
  }
}
allow rules run without a prompt — safe, repeated commands you’ve decided don’t need a checkpoint every time. ask rules pause for your confirmation before running. deny rules block the action outright, and no allow rule anywhere — project settings, user settings, nothing — can override a deny once it’s set. Rules support exact matches, prefix wildcards, and pattern wildcards, so you can allow Bash(npm:*) broadly while still denying the one destructive npm script you never want run unattended. The interactive /permissions command lets you build this list by hand as you go, approving or rejecting each new request the first time it comes up, rather than writing the whole policy up front.
Aider’s different bet: git as the safety net
Aider takes a genuinely different approach to the same problem. Rather than gating actions before they happen, it leans on git: every change Aider makes lands as its own atomic commit with a descriptive message, automatically. The safety net isn’t a permission prompt, it’s version control — if a change was wrong, you diff it, revert it, or cherry-pick around it with the same git tools you already know. Neither philosophy is strictly better. A prompt-gated system catches problems before they happen; a commit-per-change system makes every problem trivially reversible after the fact. Knowing which tool takes which bet tells you what kind of attention it actually needs from you.
Permission isn’t a checkbox you set once. It’s an ongoing decision about how much you trust this specific tool, on this specific project, today — and good tools give you the resolution to make that decision command by command, not just on or off.
The loop underneath every task
Whatever the interface, the underlying pattern is the same five-step cycle, running on its own until the task is actually finished:
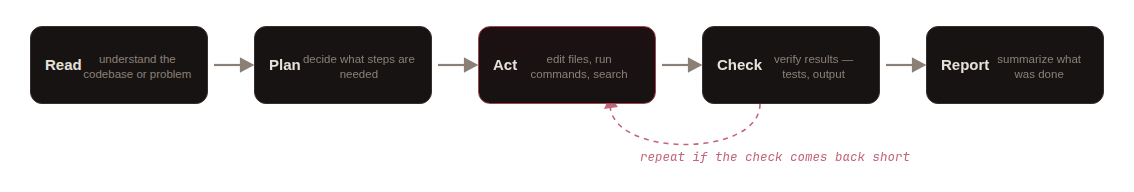
- Read — the tool opens the relevant files, greps the codebase, or runs a command to understand the current state before touching anything. It’s not guessing at what your auth middleware looks like; it’s actually looking.
- Plan — it works out what sequence of edits and commands will get from the current state to the goal. For anything non-trivial, this planning step is where a capable model genuinely earns its keep — the difference between a plan that handles the edge case and one that doesn’t shows up here, before a single file gets touched.
- Act — it edits files, runs commands, searches, whatever the plan called for. This is the step a plain chatbot simply cannot do.
- Check — it verifies the result. Run the test suite. Check the command’s exit code. Read the file back to confirm the edit landed the way it was meant to. This step is what separates a genuinely agentic tool from one that fires off actions and hopes.
- Repeat or report — if the check came back short, it loops back into acting again, now informed by what just failed, rather than stopping to ask you what to do next. Once the check passes, it reports what it did.
The loop runs on its own. You’re not driving every keystroke — you’re steering, and you can interrupt at any point to redirect it.
The check step is worth dwelling on, because it’s the one people underestimate. A tool that edits a file and moves on without running anything to confirm the edit worked is only doing half the job — it’s producing plausible-looking changes, not verified ones. The tools that are actually useful for real engineering work close that loop themselves: they run the test, read the error, and go around again, exactly the way you would if you were doing it by hand and just happened to type faster than anyone alive.
What this actually looks like, day to day
None of the following are magic incantations. They’re plain instructions — the kind you’d give a competent colleague sitting next to you, except this one already has the whole codebase loaded and doesn’t need a coffee break.
# Fix a reported bug
"The auth middleware is throwing a 401 on valid tokens. Find and fix the issue."

# Review recent work
"Review the changes I just made and check for security issues."

# Add a feature
"Add rate limiting to all /api/v2 endpoints — 100 requests per minute per IP."

# Understand unfamiliar code
"Explain what this workflow function actually does."
What actually happens behind each of those is the full loop above, usually several times over for anything beyond a one-line fix. The “add rate limiting” request, for instance, means the tool has to find every /api/v2 route (read), decide whether that calls for per-route middleware or one shared layer and which existing rate-limiting library, if any, is already a project dependency (plan), write the middleware and wire it into each route (act), run the existing test suite plus write a quick test that actually exceeds the limit and checks for the right response (check), and only then tell you it’s done — or, if the new test fails because the response code doesn’t match what the ticket asked for, quietly fix that and check again before it ever reports back.
Where to go if you want the real thing
- Claude Code overview — Anthropic’s own documentation for the terminal-based agent referenced throughout this post, including the
CLAUDE.mdconvention. - Configure permissions — Claude Code Docs — the full allow/deny/ask rule syntax, evaluation order, and the
/permissionsinteractive manager. - Claude 3.7 Sonnet and Claude Code — Anthropic’s original February 2025 announcement introducing Claude Code as a research preview.
- Aider — AI Pair Programming in Your Terminal — Aider’s own site and documentation, including how its git-native auto-commit workflow actually operates.
- anthropics/claude-code on GitHub — the project’s public issue tracker and source, useful for seeing real day-to-day usage patterns and edge cases discussed by other users.
It’s not the AI that’s new. It’s what it’s allowed to do.
The model doing the reasoning inside Claude Code isn’t a fundamentally different model from the one behind a chat window — often it’s the exact same one. What changed is the scaffolding around it: a loop that keeps running, a toolkit aimed at real files and real commands, and a permission system that lets you decide, deliberately, how much of that you’re comfortable handing over. That’s the whole unlock. Not a smarter brain. Hands, and a sensible set of rules for when they’re allowed to move.
I didn’t trust any of this on day one, and I don’t think you should either — trust it the way you’d trust a new hire, by watching what it does with a small task before you hand it a bigger one. But watch closely, because the gap between “an AI that can talk about your code” and “an AI that can actually go fix it while you do something else” is the biggest single jump in usefulness this whole series covers.